On a news site, the article is not what goes stale. Once published, it rarely changes. What goes stale is everything around it: the right-hand column with the latest news, the most read articles, the ticker at the top of the page.
On le10sport.com, that column set the cache policy for the whole page. A recent article stayed at the edge for 15 minutes at most. Not because the article changed, but because its “latest news” rail would otherwise show day-old headlines. Older articles got longer TTLs, capped at 12 hours.
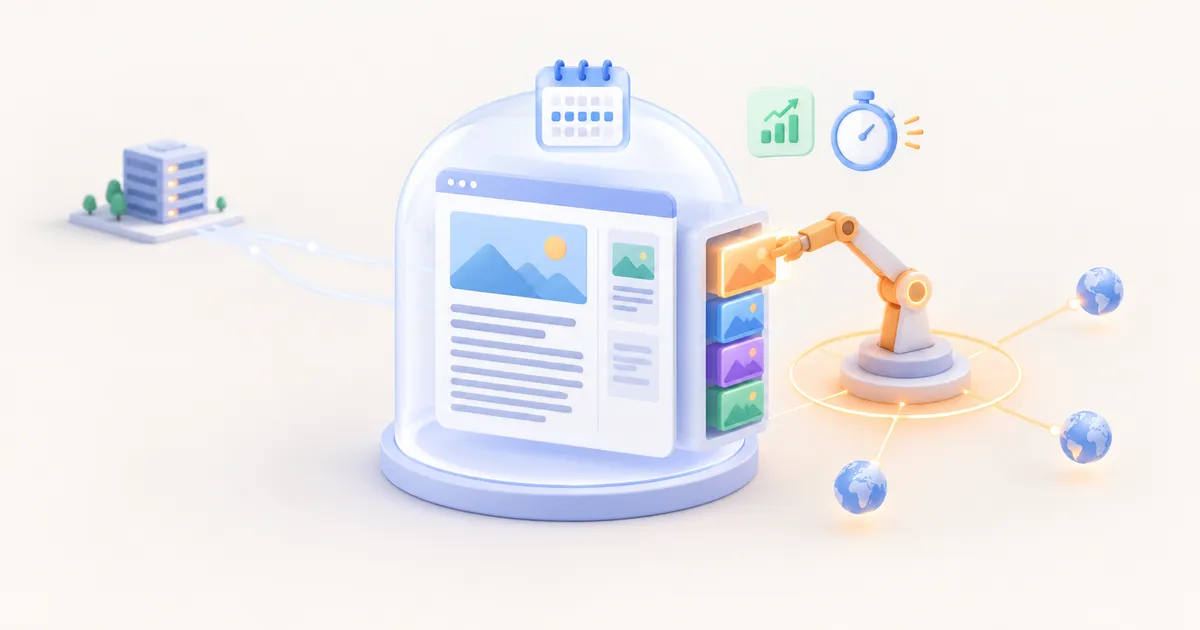
Since September 2026, every article page is cached for 7 days and the right-hand column is still up to date. The origin no longer renders the rails into the page. A Cloudflare Snippet fills them in at the edge, on every response, cache hits included.
The idea: cache the page, not the column
The page and its column don’t live at the same pace, so we stopped storing them together:
- The page is rendered by the origin with an empty placeholder where each rail goes, and cached for a week.
- The rails are rendered separately, packed into the Snippet’s code, and republished every time they change.
- The Snippet runs in front of the cache. It takes the cached page, swaps each placeholder for the current rail, and sends the result to the reader.
sequenceDiagram
  participant R as Reader
  participant S as Snippet (edge)
  participant C as Edge cache
  participant O as Origin (Cloud Run)
  R->>S: GET /article
  S->>C: fetch
  alt cache hit (7 days)
    C-->>S: page with placeholders
  else cache miss
    C->>O: render
    O-->>C: page with placeholders
    C-->>S: page with placeholders
  end
  S-->>R: page with the current rails
  Note over O,S: on publish, release or popularity change,<br/>the origin rebakes the rails into the Snippet
The page in the cache never changes when a rail changes, so nothing has to be purged. Only the Snippet is replaced.
How it works
The origin renders placeholders
Every rail that can be deferred is listed in the SEO bundle’s configuration. On le10sport, that’s 12 right-column rails plus the ticker. Instead of the rail, the origin renders an inert element:
<seo-block data-group="rightColumn" data-block="headlines" data-limit="6" data-exclude="123456" aria-busy="true">
  <!-- the rail's skeleton, so the layout doesn't move -->
</seo-block>
data-limit is how many items this page shows. data-exclude is the current
article, so an article never appears in its own “latest news” rail. The title
and the “see more” link stay in the page template, around the placeholder.
The Snippet fills them in
The Snippet uses HTMLRewriter, Cloudflare’s streaming HTML parser, to find
each <seo-block> and replace it. It applies the same rule every time: drop
the excluded item, keep the first limit. A rail the Snippet doesn’t know is
left as it is.
It only touches 200 text/html responses to GET requests. It also stamps
every page it rewrites with X-Seo-Snippet-Version, -Commit and -Built,
so you can tell from a single curl which payload a page was served with.
The rails are baked into the Snippet
The rails aren’t fetched at request time. They’re baked: a Symfony command,
seo:snippet:bake, renders every deferred rail, compresses them (gzip, then
base64), writes them into the Snippet’s code and publishes it through the
Cloudflare API. At the edge, DecompressionStream unpacks them.
The bake runs in three cases:
- On every release, from the post-release Cloud Run job, in one region only.
- On publish: the Strapi backoffice calls a webhook on the website, at most once a minute, right after reindexing the article.
- When popularity changes: the job that recomputes the most read articles asks for a rebake.
A rail is therefore as fresh as the last publication, without a single page purge.
The links stay crawlable
The rails exist for SEO as much as for readers: they’re internal links. A rail filled in by JavaScript in the browser publishes nothing to a crawler that doesn’t run it. Filling it in at the edge means the HTML that Googlebot receives already contains the links.
The bake goes one step further. Each link is baked as an obfuscated
<span data-seo-link>, and the Snippet turns it back into a real <a> only if
this page’s SEO rules allow it and the page doesn’t already link to the same
URL. The page tells the Snippet which URLs it already links through a Bloom
filter in a small JSON script. So the rules that decide which links are
crawlable apply to the rails too, even though the rails were rendered once for
thousands of pages.
What it changes
Traffic to the origin
The article pages’ CDN TTL went from a ladder based on article age (15 minutes for the first two days, then up to 12 hours) to a flat 7 days. On paper, a fresh article now goes back to the origin up to 672 times less often (every 15 minutes → once a week), and the oldest ones 14 times less often.
Here is what actually changed. The change shipped on 8 September and was fully in effect from 10 September; the days in between were a transition, with an internal SEO crawl on the 9th on top, so they’re left out. The averages compare 29 August – 7 September with 11 – 22 September. Cloudflare’s numbers are for the whole zone; the origin numbers come from Cloud Run, both production regions combined:
| Per day, on average | Before | After | Change |
|---|---|---|---|
| Requests to the zone | 3.56 M | 3.04 M | −15 % |
| Share served from the edge cache | 59.0 % | 74.4 % | +15 pts |
Revalidations of expired pages (EXPIRED) | 178,000 | 25,000 | −86 % |
Background refreshes (UPDATING) | 174,000 | 19,500 | −89 % |
| Requests reaching the website on Cloud Run | ~400,000 | ~140,000 | ÷2.8 |
The two middle lines are the TTL at work. With 15-minute pages, the edge spent
its days going back to the origin to refresh pages it already had, either
blocking the reader (EXPIRED) or in the background while serving the stale
copy (UPDATING): 350,000 refreshes a day. With a week, those refreshes all but
disappeared. The edge now serves three requests out of four from its cache,
against three out of five before, and the origin gets 2.8 times fewer
requests. Traffic to the zone itself was 15 % lower over the second period,
which accounts for a small part of that; the rest is the cache. Article pages
alone, sampled in the Cloud Run logs over half-hour windows at three times of
day, went from about 5,600 to about 2,200 requests per half hour, a similar
ratio.
The gap between 672× and 2.8× is the most useful lesson here. The access logs show who still reaches the origin: three quarters of it is crawlers (Googlebot, Bing, Ahrefs, Semrush…), before and after. Our reading of it: crawlers walk the long tail of old articles, and each of those URLs is requested so rarely that it’s seldom in the cache of the Cloudflare location a crawler happens to hit. For those pages the old TTL was already 12 hours, so the gain there is small. The readers’ traffic, concentrated on recent articles, is where the week of cache works.
The rails themselves cost the origin nothing per request. They’re rendered once per bake, not once per page view.
Performance
Cloudflare measures the time to first byte of every HTML response at the edge. Same periods:
| Edge TTFB, HTML pages | Before | After | Change |
|---|---|---|---|
| p50 | 15.9 ms | 26.8 ms | +10.9 ms |
| p90 | 252 ms | 187 ms | −65 ms (−26 %) |
| Mean | 85.7 ms | 74.0 ms | −11.7 ms |
The tail is where it shows. Before, one page view in ten waited a quarter of a second or more, most often for a page to come back from Cloud Run. Now far fewer requests go that far, and the p90 drops by a quarter. One caveat: on 16 September, in the middle of the second period, the website also started scaling to zero. That makes the requests that do reach the origin more likely to hit a cold start, so if anything it works against the p90.
The median goes the other way: about 11 ms more. The substitution itself is
close to free. Measured in workerd, Cloudflare’s open-source runtime:
- decoding a 12-rail payload: 0 ms at p50, 1 ms at p90;
- replacing 12 placeholders in a page: 1.27 ms at p50, against 1.16 ms for a page with nothing to replace;
- the
limitandexcludestep: about 60 µs per placeholder.
So the extra median is most likely the cost of having a Snippet on the path of every HTML response at all: its start-up and the page being streamed through a rewriter, where it used to leave the cache as is. We accept about 11 ms at the median for 65 ms at p90 and a fresh right column.
On a 750g staging test, a page served as a cache hit carried the freshly baked rails while the Cloud Run logs showed no request at all. The edge does all the work.
Cost
Three lines move:
- Cloud Run. The service is billed while an instance serves requests, plus the time of any instance kept warm. Fewer requests means less billed time: the edge now absorbs about two thirds of the requests that used to reach the origin. The biggest line was elsewhere, though. Until 16 September, one instance per region stayed warm permanently, which alone made ~173,000 billable instance-seconds a day. The service now scales to zero, and billed time dropped to ~15,000 seconds a day, eleven times less. That setting is independent of the Snippet, but the fewer requests reach the origin, the more scaling to zero pays off.
- Cloudflare. Snippets are included in every paid plan. They add no per-request cost, even though they run on every page view.
- Operations. Nothing to purge, so no purge fan-out and no page-level cache tags.
Why Snippets rather than Workers
The first version was a Worker. It was built and tested (56 tests) and never deployed. Snippets won for three reasons.
Cost. A Worker runs on the same requests a Snippet does, cache hits included, and it’s billed per request. The whole point of this setup is to serve almost everything from the cache, and a Worker would bill every one of those hits. Our design notes put it this way: a Cloud Run request costs roughly ten times a Worker invocation, but the Worker fires on perhaps a hundred times more requests. Snippets, included in the plan, remove that line entirely.
Same runtime. Snippets run on the same engine as Workers: HTMLRewriter,
fetch and the Web Streams APIs are all there. We didn’t have to give up
anything we needed.
Baking makes the limits irrelevant. Snippets are stricter than Workers:
| Limit | Snippet |
|---|---|
| Code size | 32 KB |
| CPU time | 5 ms |
| Memory | 2 MB |
| Subrequests | 5 |
Secrets, env, waitUntil | none |
A version that fetched each rail at request time needed 13 subrequests on an article page, and it would have needed a secret to reach the origin. Baking the rails into the code removes both: no subrequest, no secret. What’s left is the 32 KB limit, which gzip handles. le10sport’s 12 rails take 13.6 KB.
What we learned along the way
- The 32 KB limit counts the uploaded bytes, not the compressed ones.
Compression has to happen inside the code, with gzip plus base64 and
DecompressionStream, which is undocumented for Snippets but works. - Not everything fits. The homepage’s 12 sections would need about 70 KB. They stay rendered by the origin, and the homepage relies on a purge when it is saved instead.
- A rail can only be deferred if it’s the same everywhere. It’s baked once and served into thousands of pages, so none of its inputs can depend on the page. A rail filtered by the article’s tag can’t be deferred.
- A Snippet without a rule does nothing, silently. The bake now publishes
its own rule. And since staging and production share one Cloudflare zone,
each environment has its own Snippet name,
seo_edge_stgandseo_edge. - A failed bake keeps the previous payload. It doesn’t fail the release. We bake from one region only: two regions baking one after the other let a degraded second pass overwrite a good first one.
- Conditional requests need care. A browser revalidating with
If-None-Matchcould get a304for a page whose rails changed since. The Snippet drops validators older than the last bake. - Watch what’s already in the cache. Pages cached before a change in the Snippet’s contract keep the old shape for up to a week. On le10sport, that once meant a week of articles that weren’t filled in.
Where it runs
le10sport.com has run this in production since 10 September 2026. The mechanism
started as a pilot on the 750g rebuild and now lives in the shared
webedia/seo-bundle (4.4), so any site on the bundle can defer its own rails.
It’s being prepared for the Pure sites.
If your pages are cached for minutes only because of a sidebar, the sidebar is what should change, not the page.