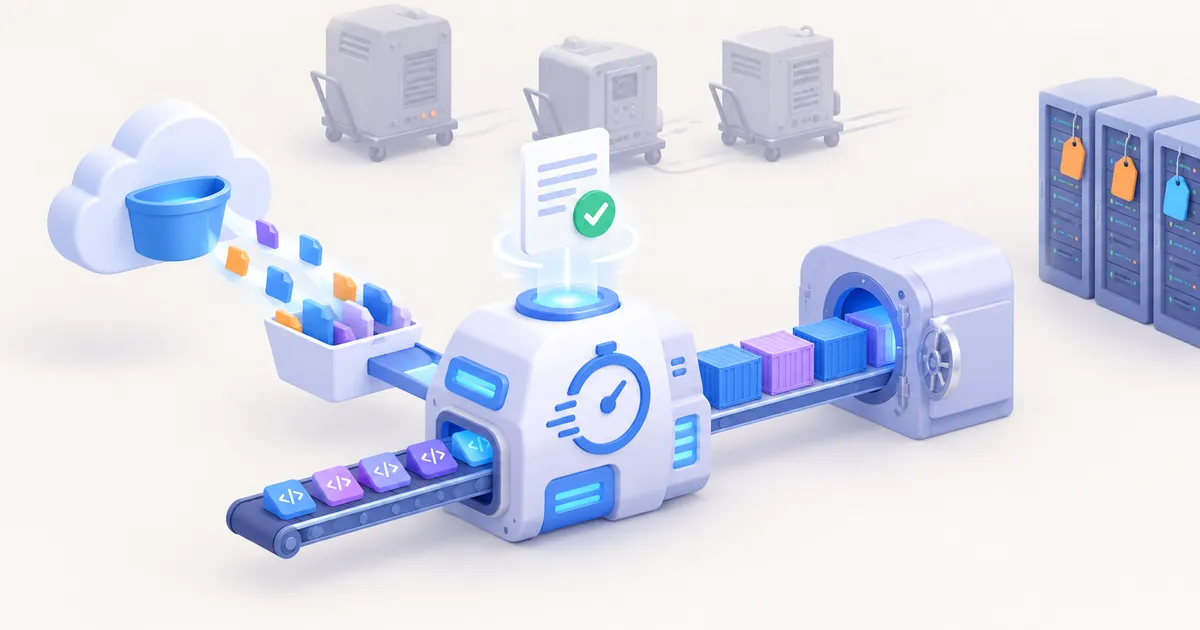
Until this month, deploying le10sport.com meant sending three builds to Cloud Build (the Symfony website, the Strapi backoffice and an imgproxy image) after a separate GitLab job had already run the tests in a CI image of its own. The last 32 staging deploys took 901 seconds on average.
Now a single GitLab job runs a single docker buildx bake. That one call runs
the checks, builds the asset bundle and pushes every image. A full staging
deploy takes 180 to 190 seconds, and a merge request pipeline takes about
95.
This post covers the three pieces that make it work: bake as the single build entry point, a BuildKit cache kept in the GitLab registry, and runner tags chosen per job.
Why Cloud Build had to go
Cloud Build itself wasn’t slow. The time went into everything around it:
- Three submissions, three cold starts. Each image uploaded its own context and started from nothing, and none of the three shared anything with the others.
- The same work, done twice. The test job installed Composer dependencies and built the assets, and then the Cloud Build image did it all again.
- A CI image nobody deployed. The tests ran in an image that had to be built, pushed to the GitLab registry and pulled back (about 20 s) for roughly 12 s of actual checks.
- Two identities. Cloud Build deployed with its own service account, and GitLab with another. Two permission sets to maintain, and deploy logs in two places.
One bake, five targets
docker buildx bake reads an HCL file
that describes several build targets and solves them in one BuildKit graph.
Targets that share Dockerfile stages build those stages once. That property is
the whole point here.
The website Dockerfile is split so that each expensive step is its own stage:
flowchart LR
  base --> php_deps
  php_deps --> builder
  builder --> assets
  base --> ci
  php_deps -. vendor-dev .-> ci
  assets -. manifests .-> ci
  ci --> test --> reports
  base --> production
  php_deps -.-> production
  assets -.-> production
docker-bake.hcl then exposes one target per output:
| Target | Dockerfile stage | Output |
|---|---|---|
website | production | runtime image, pushed to Artifact Registry |
test | reports | junit report + exit status, as local files |
assets | assets | built JS/CSS, as local files for the CDN |
backoffice | own Dockerfile | Strapi image, pushed to Artifact Registry |
imgproxy | own Dockerfile | re-tagged upstream image |
test and assets inherit from website and only override the stage and the
output:
target "test" {
  inherits = ["website"]
  target   = "reports"
  tags     = []
  output   = ["type=local,dest=${REPORTS_OUTPUT_DIR}"]
}

target "assets" {
  inherits = ["website"]
  target   = "assets"
  tags     = []
  output   = ["type=local,dest=${ASSETS_OUTPUT_DIR}"]
}
Because they share the same context, build args and stages, the Composer install and the Vite build run once for all three.
Tests as a build stage
The checks (PHPUnit, PHPStan, php-cs-fixer) no longer run in their own job. They’re a stage of the Dockerfile:
FROM ci AS test
ARG TEST_RUN_ID
RUN ...checks...; echo $status > /reports/checks.status

FROM scratch AS reports
COPY --from=test /reports /
Three details matter:
- The
RUNrecords the result instead of failing on it. A red PHPUnit still exports its junit report, and a PHPStan error isn’t hidden behind it. The job then exits with the recorded status:exit "$(cat reports/checks.status)". TEST_RUN_IDis the pipeline id. It’s declared only in that stage, so the checks run on every pipeline while everything above stays cached. Otherwise a cached red result would stick to the commit.- Nothing is pushed. The junit report goes straight to GitLab’s test widget as an artifact.
Assets as files
The CDN bucket needs the built JS/CSS as files, not as an image. A
FROM scratch AS assets stage holds only the bundle, and bake exports it to a
directory that the deploy job uploads with gcloud storage rsync. The runtime
image carries its own copy of the same files, since it serves manifest.json.
One trap: pushing is done with output = ["type=registry"] on each image
target, not with --push. --push applies to every target and would override
the local export, and the assets directory would then come out empty.
Merge requests build less
The same job runs on merge requests with BAKE_TARGETS: "test", and on deploy
pipelines with "test website assets backoffice imgproxy". A merge request
builds the checks and the bundle they need, and nothing it would never deploy.
The cache lives in the GitLab registry
Images go to Artifact Registry, as before. The BuildKit cache goes
somewhere else: the project’s own GitLab registry,
$CI_REGISTRY_IMAGE/website-cache. That’s the one registry a job token can
write to, whichever environment the pipeline deploys to, so there are no extra
credentials per environment.
cache-from = ["type=registry,ref=${CACHE_IMAGE}:website",
              "type=registry,ref=${CACHE_IMAGE}:ci"]
cache-to   = ["type=registry,ref=${CACHE_IMAGE}:website,mode=max,image-manifest=true,oci-mediatypes=true,ignore-error=true"]
What we learned along the way:
mode=maxexports the intermediate stages (php_deps,builder) as well as the final one, and those are where the time goes.- One cache tag per exporter.
websitewrites:websiteandtestwrites:ci. Two exporters writing the same tag race each other.websitereads both tags, so a deploy starts from what the merge request left behind. ignore-error=true. The cache is best effort. If a registry refuses the write, the next build loses its cache, but this build doesn’t fail.- Keep the cache away from images. When a CI image was pushed to GitLab
next to its cache, the export failed with
blob unknown to registryunless every layer was recompressed. Now the only thing in that repository is the cache. - Secrets are mounted, never copied. The Composer
auth.jsonand the npm.npmrcare BuildKit secrets. Withmode=max, aCOPY auth.jsonwould end up in a cached layer that anyone with registry read access could pull.
buildkitd as a service, not dind
The build job uses the docker CLI with a
moby/buildkit service, reached
through buildx’s remote driver:
build:
  image: docker:29
  services:
    - name: moby/buildkit:v0.33.0
      alias: buildkit
      command: ['--addr', 'tcp://0.0.0.0:1234']
  before_script:
    - docker buildx create --name builder --driver remote tcp://buildkit:1234 --use
  script:
    - make bake
Docker-in-Docker took about 17 s to come up, and buildx then started its own
BuildKit container inside it, which took another ~6 s and pulled the image
every time. buildkitd accepts connections as soon as it starts, and the
remote driver forwards the registry logins, the secrets and the local exports
from the client.
The pipeline, end to end
flowchart LR
  auth[gcp-auth<br/>standard-spot] --> build[build<br/>bake: test + images + assets<br/>perf-spot]
  build --> deploy[deploy website<br/>standard-ondemand]
  build --> bo[deploy backoffice<br/>standard-ondemand]
  build --> img[deploy imgproxy<br/>standard-ondemand]
The deploy jobs have nothing left to build. The website rollout uploads the
bundle first (HTML that references a hashed file must never be served
before that file is in the bucket), deploys the Cloud Run revision in each
region with set -e, and only then moves the latest tag onto the image. That
way latest only ever points to an image that passed the checks and actually
serves traffic. Each service takes its own resource_group, so two merges a
few minutes apart can’t race on the traffic switch.
Pick the runner by tag
The last piece isn’t about Docker. Our GitLab runners come in tiers, and
the shared base CI component
exposes each tier as an anchor:
| Tier | Tag | Machine | Use it for |
|---|---|---|---|
standard-ondemand | wbd-docker-standard-ondemand | n4d-standard-4, 4 vCPU | the default: deploys, terraform, gcloud |
standard-spot | wbd-docker-standard-spot | same, preemptible | light jobs that can be retried |
perf-ondemand | wbd-docker-perf-ondemand | c4d-standard-8-lssd, 8 vCPU + local NVMe | heavy jobs that must not be interrupted |
perf-spot | wbd-docker-perf-spot | same, preemptible | heavy jobs that can be retried |
The tag reads wbd-<executor>-<profile>-<provisioning>. You never write it
by hand. Each anchor bundles the tag and a retry on
runner_system_failure, which is how GitLab reports a spot preemption.
extends a job onto a tier:
build:
  extends: .runner-perf-spot
The fleet-wide default is set differently. GitLab’s top-level default:
keyword can’t extends, so it wires both keys explicitly:
default:
  tags: !reference [.runner-standard-spot, tags]
  retry: !reference [.runner-standard-spot, retry]
Never !reference the tags alone on a spot tier: the job would lose its retry,
and a preemption would show up as a failure.
Here is how le10sport picks a tier for each job:
- Everything defaults to
standard-spot. Auth and small jobs are cheap to replay, so there’s no reason to pay the on-demand rate for them. - The bake runs on
perf-spot. Twice the CPU, and BuildKit’s layers sit on a local NVMe SSD instead of a network disk: 35 s instead of 63 s measured. It’s still spot. If the job is preempted it’s retried, and the registry cache means the retry starts warm. - The deploys run on
standard-ondemand. Every step can technically be replayed, but a preemption there is expensive. The job holds the service lock and spends most of its time waiting on a Cloud Run job. A preemption replays the whole rollout, and in the meantime the new revision serves traffic without its post-release step. Reliability matters more than the discount here.
In short: use spot by default, use perf where CPU and disk are the
bottleneck, and use on-demand only where an interruption costs more than the
job itself.
Why it’s faster
No single change explains the drop from ~15 minutes to ~3. It comes from removing work at every level:
- Work that used to be done twice is now done once. The Composer install
and the Vite build used to run in the test job and then again in each Cloud
Build image. Now
test,websiteandassetssharephp_depsandbuilderinside one BuildKit graph, so each is computed once per pipeline. - The cache starts warm. Each Cloud Build submission started from a cold
builder. Now every stage, intermediate ones included (
mode=max), is pulled from the registry cache. On a typical commit, only the layers the change touched are rebuilt, and the rest is a cache hit. - Changing one layer doesn’t invalidate the rest. The Dockerfile is
ordered so that the expensive steps don’t depend on what changes most often.
Dependencies live in their own stage. Per-environment
ARGs are declared just before the Vite build. The Vite build only copies what Vite reads. A PHP- or Twig-only commit therefore rebuilds neither the dependencies nor the bundle. - Less moving around. No CI image is pushed and pulled back (~20 s saved). No build context is uploaded three times. Reports and assets leave the build as files, not as images.
- Less startup. One job instead of a test job plus three builds. BuildKit runs as a service that’s ready immediately, which avoids ~17 s of Docker starting up and ~6 s of buildx booting its own builder.
- Faster hardware where it matters. The bake runs on the
perftier, with twice the CPU and BuildKit’s layers on a local NVMe SSD: 35 s instead of 63 s for the same build. - Everything else runs in parallel. The three deploy jobs start as soon as the bake finishes, instead of each waiting on its own Cloud Build.
Takeaways
- One bake means one graph. Tests, assets and images that share stages should be built in the same call, so the shared stages are computed once.
- Not every output has to be an image. Exporting reports and bundles as local files removes a push, a pull and a job.
- Keep the cache in a registry every pipeline can write to, with one tag
per exporter and
ignore-error=true. - Pick the runner for each job by what it costs to lose it. The tier
anchors in
basemake that a one-line decision.
The full setup is in le10sport’s
docker-bake.hcl
and .ci/app-gitlab-ci.yml.
Every non-obvious line has a comment explaining why it’s there.